Wednesday, January 3, 2024

Using FastAPI for an OpenAI chat backend

When building web APIs that make calls to OpenAI servers, we really want a backend that supports concurrency, so that it can handle a new user request while waiting for the OpenAI server response. Since my apps have Python backends, I typically use either Quart, the asynchronous version of Flask, or FastAPI, the most popular asynchronous Python web framework.

In this post, I'm going to walk through a FastAPI backend that makes chat completion calls to OpenAI. Full code is available on GitHub: github.com/pamelafox/chatgpt-backend-fastapi/


Initializing the OpenAI client

In the new (>= 1.0) version of the openai Python package, the first step is to construct a client, using either OpenAI(), AsyncOpenAI(), AsyncOpenAI, or AzureAsyncOpenAI(). Since we're using FastAPI, we should use the Async* variants, either AsyncOpenAI() for openai.com accounts or AzureAsyncOpenAI() for Azure OpenAI accounts.

But when do we actually initialize that client? We could do it in every single request, but that would be doing unnecessary work. Ideally, we would do it once, when the app started up on a particular machine, and keep the client in memory for future requests. The way to do that in FastAPI is with lifespan events.

When constructing the FastAPI object, we must point the lifespan parameter at a function.

app = fastapi.FastAPI(docs_url="/", lifespan=lifespan)

That lifespan function must be wrapped with the @contextlib.asynccontextmanager decorator. The body of the function setups the OpenAI client, stores it as a global, issues a yield to signal it's done setting up, and then closes the client as part of shutdown.

from .globals import clients


@contextlib.asynccontextmanager
async def lifespan(app: fastapi.FastAPI):
    
    if os.getenv("OPENAI_KEY"):
         # openai.com OpenAI
        clients["openai"] = openai.AsyncOpenAI(
            api_key=os.getenv("OPENAI_KEY")
        )
    else:
        # Azure OpenAI: auth is more involved, see full code.
        clients["openai"] = openai.AsyncAzureOpenAI(
            api_version="2023-07-01-preview",
            azure_endpoint=os.getenv("AZURE_OPENAI_ENDPOINT"),
            **client_args,
        )

    yield

    await clients["openai"].close()

See full __init__.py.

Unfortunately, FastAPI doesn't have a standard way of defining globals (like Flask/Quart with the g object), so I am storing the client in a dictionary from a shared module. There are some more sophisticated approaches to shared globals in this discussion.


Making chat completion API calls

Now that the client is setup, the next step is to create a route that processes a message from the user, sends it to OpenAI, and returns the OpenAI response as an HTTP response.

We start off by defining pydantic models that describe what a request looks like for our chat app. In our case, each HTTP request will contain JSON with two keys, a list of "messages" and a "stream" boolean:

class ChatRequest(pydantic.BaseModel):
    messages: list[Message]
    stream: bool = True

Each message contains a "role" and "content" key, where role defaults to "user". I chose to be consistent with the OpenAI API here, but you could of course define your own input format and do pre-processing as needed.

class Message(pydantic.BaseModel):
    content: str
    role: str = "user"

Then we can define a route that handles chat requests over POST and send backs a non-streaming response:

@router.post("/chat")
async def chat_handler(chat_request: ChatRequest):
	messages = [{"role": "system", "content": system_prompt}] + chat_request.messages
    response = await clients["openai"].chat.completions.create(
    	messages=messages,
    	stream=False,
    )
    return response.model_dump()

The auto-generated documentation shows the JSON response as expected:

Screenshot of FastAPI documentation with JSON response from OpenAI chat completion call


Sending back streamed responses

It gets more interesting when we add support for streamed responses, as we need to return a StreamingResponse object pointing at an asynchronous generator function.

We'll add this code inside the "/chat" route:

if chat_request.stream:
    async def response_stream():
        chat_coroutine = clients["openai"].chat.completions.create(
            messages=messages,
            stream=True,
        )
        async for event in await chat_coroutine:
            yield json.dumps(event.model_dump(), ensure_ascii=False) + "\n"

    return fastapi.responses.StreamingResponse(response_stream())

The response_stream() function is an asynchronous generator, since it is defined with async and has a yield inside it. It uses async for to loop through the asynchronous iterable results of the Chat Completion call. For each event it receives, it yields a JSON string with a newline after it. This sort of response is known as "json lines" or "ndjson" and is my preferred approach for streaming JSON over HTTP versus other protocols like server-sent events.

The auto-generated documentation doesn't natively understand streamed JSON lines, but it happily displays it anyways:

Screenshot of FastAPI server response with streamed JSON lines


All together now

You can see the full router code in chat.py. You may also be interested in the tests folder to see how I fully tested the app using pytest, extensive mocks of the OpenAI API, including Azure OpenAI variations, and snapshot testing.

Using llamafile for local dev for an OpenAI Python web app

We're seeing more and more LLMs that can be run locally on a laptop, especially those with GPUs and multiple cores. Open source projects are also making it easier to run LLMs locally, so that you don't have to be an ML engineer or C/C++ programmer to get started (Phew!).

One of those projects is llamafile, which provides a single executable that serves up an API and frontend to interact with a local LLM (defaulting to LLaVa). With just a few steps, I was able to get the llamafile server running. I then discovered that llamafile includes an OpenAI-compatible endpoint, so I can point my Azure OpenAI apps at the llamafile server for local development. That means I can save costs and also evaluate the quality difference between deployed models and local models. Amazing!

I'll step through the process and share my sample app, a FastAPI chat app backend.

Running the llamafile server

Follow the instructions in the quickstart to get the server running.

Test out the server by chatting with the LLM:

Screenshot of llama.cpp conversation about haikus

Using the OpenAI-compatible endpoint

The llamafile server includes an endpoint at "/v1" that behaves just like the OpenAI servers. Note that it mimics the OpenAI servers, not the *Azure* OpenAI servers, so it does not include additional properties like the content safety filters.

Test out that endpoint by running the curl command in the JSON API quickstart.

You can also test the Python code in that JSON quickstart to confirm it works as well.

Using llamafile with an existing OpenAI app

As the llamafile documentation shows, you can point an OpenAI Python client at a local server by overriding base_url and providing a bogus api_key.

client = AsyncOpenAI(
    base_url="http://localhost:8080/v1",
    api_key = "sk-no-key-required"
)

I tried that out with one of my Azure OpenAI samples, a FastAPI chat backend, and it worked for both streaming and non-streaming responses! 🎉

Screenshot of response from FastAPI generated documentation for a request to make a Haiku

Switching with environment variables

I wanted it to be easy to switch between Azure OpenAI and a local LLM without changing any code, so I made an environment variable for the local LLM endpoint. Now my client initialization code looks like this:

if os.getenv("LOCAL_OPENAI_ENDPOINT"):
    client = openai.AsyncOpenAI(
    	api_key="no-key-required",
        base_url=os.getenv("LOCAL_OPENAI_ENDPOINT")
    )
else:
    # Lots of Azure initialization code here...
    # See link below for full code.
    client = openai.AsyncAzureOpenAI(
      api_version="2023-07-01-preview",
      azure_endpoint=os.getenv("AZURE_OPENAI_ENDPOINT"),
      # plus additional args
    )

See full code in __init__.py.

Notice that I am using the Async version of the OpenAI clients in both cases, since this backend uses FastAPI and 100% asynchronous calls. For llamafile, I don't bother using the Azure version of the client, since llamafile is only trying to mimic the openai.com servers. That should be fine, as I typically code assuming the openai.com servers as a baseline, and just taking advantage of Azure extras (like content safety filters) when available.

I will likely try out llamafile for my other Azure OpenAI samples soon, and run some evaluations to see how llamafile compares in terms of quality. I don't have any plans to use non-OpenAI models in production, but I want to keep monitoring how well the local LLMs can perform and what use cases there may be for them.

Friday, December 29, 2023

Santa Tracker Tales: Nearly crashing Google's servers, Leaking Santa's data, and Angering an entire country

Back when I worked at Google, from 2006-2011, I spent many a December on my 20% project, the Santa Tracker. In those days, the tracker was a joint collaboration with NORAD, with the Googlers focused on making the map that showed Santa's journey across the world. I was brought in for my expertise with the Google Maps API (as my day job was Maps API advocacy), and our small team also included an engineer, an SRE, and a marketing director. It was a formative experience for me, since it was my first time working directly on a consumer-facing website. Here are the three incidents that stuck with me the most...

Nearly crashing Google's servers

Here's what the tracker map looked like:

Screenshot of Google map with Santa marker and presents

The marker is a Santa icon, it's positioned on top of his current location, and there's a sparkly trail showing his previous locations, so that families could see his trajectory.

We programmed the map so that Santa's moves were coordinated globally: we knew ahead of time when Santa should be in each location, and when the browser time ticked forward to a matching time, the Santa marker hopped to its next location. If 1 million people had the map open, they'd all see Santa move at the same time.

That hop was entirely coded in JavaScript, just a re-positioning of map markers, so it shouldn't have affected the Google servers, right? But our SRE was seeing massive spikes in the server's usage graphs every 5 minutes, during Santa's hops, and was very concerned the servers wouldn't be able to handle increased traffic once the rest of the world tuned in (Santa always started in Australia/Japan and moved west).

So what could cause those spikes? We thought at first it could be the map tiles, since some movements could pan the map enough to load in more tiles... but our map was fairly zoomed out, and most nearby tiles would have been loaded in already.

It was the sparkly trail! My brilliant addition for that year was about to crash Google's servers. The trail was a collection of multiple animated GIFs, and due to the way I'd coded it, the browser made a new img tag for each of them on each hop. And, as you may have guessed by now, there were no caching headers on those GIFs, and no CDN hosting them. Every open map was making six separate HTTP requests at the exact same time. Eek!

Our SRE quickly added in caching headers, so that the browsers would store the images after initial page load, and the Google servers were happy again.

Lesson learned: Always audit your cache headers!

Leaking Santa's data

How did the map know which location Santa should visit next? Well, if a 4 year old is reading this, it sent a request to Santa's sleigh's GPS. For the rest of you, I'll reveal the amazing technology backing the map: a Google spreadsheet.

We coordinated everything via a spreadsheet, and even used scripts inside the sheet to verify the optimal ordering of locations. We needed Santa to visit each of the locations before 10 pm in the local time zone, since one of goals of the tracker is to help parents get kids to bed by showing them that Santa's on his way. That meant a lot of zig zagging north to south, and some back and forth zig zagging to accomodate for time zone differences across countries.

We published that spreadsheet, so that the webpage could fetch its JSON feed. I think there were some years that we converted the spreadsheet to a straight JSON object in a js file, but there was at least one year where we fetched the sheet directly. That gave us the advantage of being able to easily update the data for users loading the map later.

We worried a bit that someone would see the spreadsheet and publish the locations, spoiling the surprise for fellow map watchers, but would someone really want to ruin the magic of Xmas like that?

Yes, yes, they would! We discovered somehow (perhaps via a Google alert) that a developer had written a blog post in Japanese describing their discovery of Santa's future locations in a neatly tabulated format. Fortunately, the post attracted little attention, at least in the English-speaking news that we could see.

Lesson learned: Security by obscurity doesn't work if your code and network requests can be easily viewed.

Angering an entire country with my ignorance

This is the most embarrassing, so please try to forgive me.

Background: I grew up in Syracuse, New York. I have fond memories of taking road trips with my family to see Niagara Falls in Toronto. The falls were breathtaking every time.

Fast forward 15 years: I'd been monitoring the map for 20 hours by the time Santa made it to the Americas, so I was pretty tired. I spent a lot of those hours responding to emails sent to Santa, mostly from adorable kids with their wishlists, but also a few from parents troubleshooting map issues. I loved answering those emails as PamElfa, my elf persona.

Suddenly, after Santa hopped to Toronto, we got a flood of angry emails. Why, they rightly wanted to know, did the info window popup say "Toronto, US" instead of "Toronto, CA"?

Oops. I had apparently managed to become a full-grown adult without realizing that Toronto is in an entirely different country. I hadn't remembered border crossing in my memories, so I had come to think that Toronto was in New York, or that at least half of it was. (How would that even work?? Sigh.)

I fixed that row in the data, but thousands had already seen the error of my ways, so I spent hours sending apology emails to justifiably upset Canadians (many of whom were quite kind about my mistake). So sorry, again, Canada!

Lesson learned: Double-check geopolitical data, especially when it comes to what cities belong to what countries.

Thursday, December 28, 2023

How to document a native California garden

Ever since moving into our house in 2021 in the East Bay area, I’ve been replacing the exotic and invasive plants with native California plants, preferring pollinator-friendly keystone species in particular.

Our garden will be part of a native gardens tour in 2024, and one of the requirements is to clearly label the native plants. I considered many label options (like marker-on-plastic or laser etched wood) but I really wanted a highly informative sign. Fortunately, Calscape.org includes a feature for printing out signs for each native California plant species, so I decided to put laminated Calscape signs around the garden. Here’s what a finished sign looks like:

Photo of a laminated plant sign on a landscape staple

If you’d like to make similar signs for your native California garden, you can follow the guide below. If your garden is in another state, you’ll need to find a similar source for signs or make them yourself.


Supplies

For convenience, I’ve linked each supply to the product I purchased on Amazon, but many products would work similarly.


Steps

  1. Make a spreadsheet of the native plants in your garden, with columns for common name and latin name. You might also want to note where you sourced the plant from and where you planted it.
  2. For each row, look up the plant on Calscape.org and add the URL to the sheet. If the entry doesn’t yet have a photo, you can add one yourself by joining the site and editing the page. Spreadsheet of plants
  3. While you have the plant page open, scroll down and select “Print plant sign”. Save it as a local PDF file or immediately print it.
  4. Print each sign on a sheet of heavyweight paper.
  5. Cut each sign on the bottom, and top as needed, so that it will fit inside pouch. The Calscape signs have variable height, so the amount of cutting required varies as well.
  6. For more rigidity, stack the sign on top of the bottom half of the paper that you cut off. Insert stack into a laminating pouch.
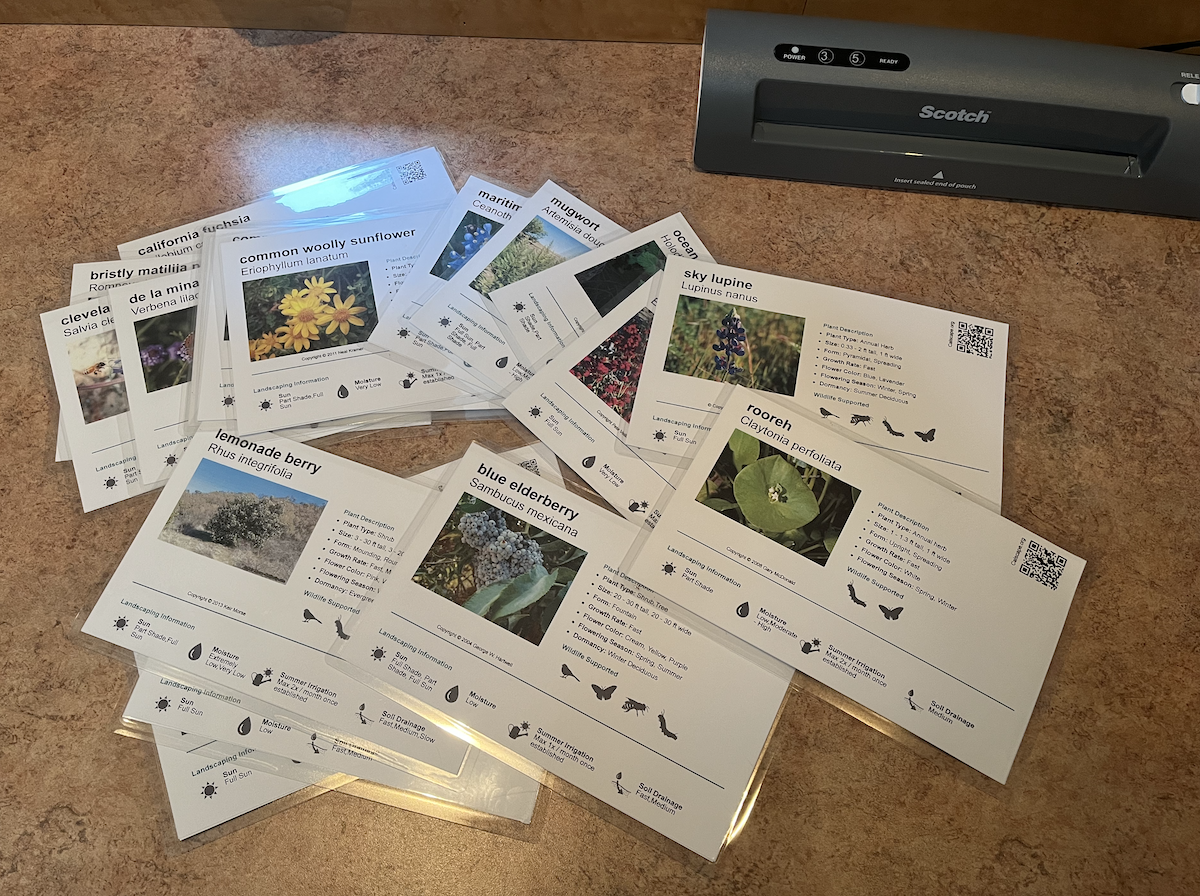
  7. Send pouch through laminating machine, and let it cool down for a few minutes. Laminator next to many laminated signs
  8. Take a landscape staple and bend the top, using either a vise or a hard countertop. A hand bending a staple over a countertop
  9. Attach sign to staple using shipping tape. The back of a laminated sign next to a roll of tape and staple
  10. Stick signs in the ground. 🎉 Photo of laminated plant signs in garden

Considerations

  • Sign size: These are fairly large signs, so they’ll stand out from afar and may encroach on plant space. I will probably also experiment with the small “plant label” option on Calscape, which only has the name and QR code. The small version seems especially helpful for labeling annual flowers that can pop up all over the place.
  • Sign color: One of the reasons the signs stand out so much is the bright white paper. I may try a cream colored paper instead, if I can find a heavyweight option, but I worry about the effect on the flower photos in each sign (especially for white flowers).
  • Weather: My first batch of signs have survived a rainstorm, so that’s promising. It remains to be seen how they will handle a full rainy season, and how much they’ll fade from repeated UV exposure. I assume I will have to remake them at some point, which is why I invested in the printer/laminator versus using a print shop.
  • Customizability: I would love to indicate plant source (seed company or nursery) but that’s not possible with the generic Calscape signs. I might end up adding small labels for the tour.

Tuesday, December 19, 2023

My failed attempt at using a closet as an office

My partner and I both work from home. I'm very thankful for that as we have two young children and a commute would take up the same time we spend on getting them ready for the day. However, it's been quite a journey coming up with a home office setup that works for both of us.

We're fortunate that our 2-bedroom house in the bay area is fairly roomy - large living room, large bedroom, and a large addition to the house that looks very much like it was designed to be an office.

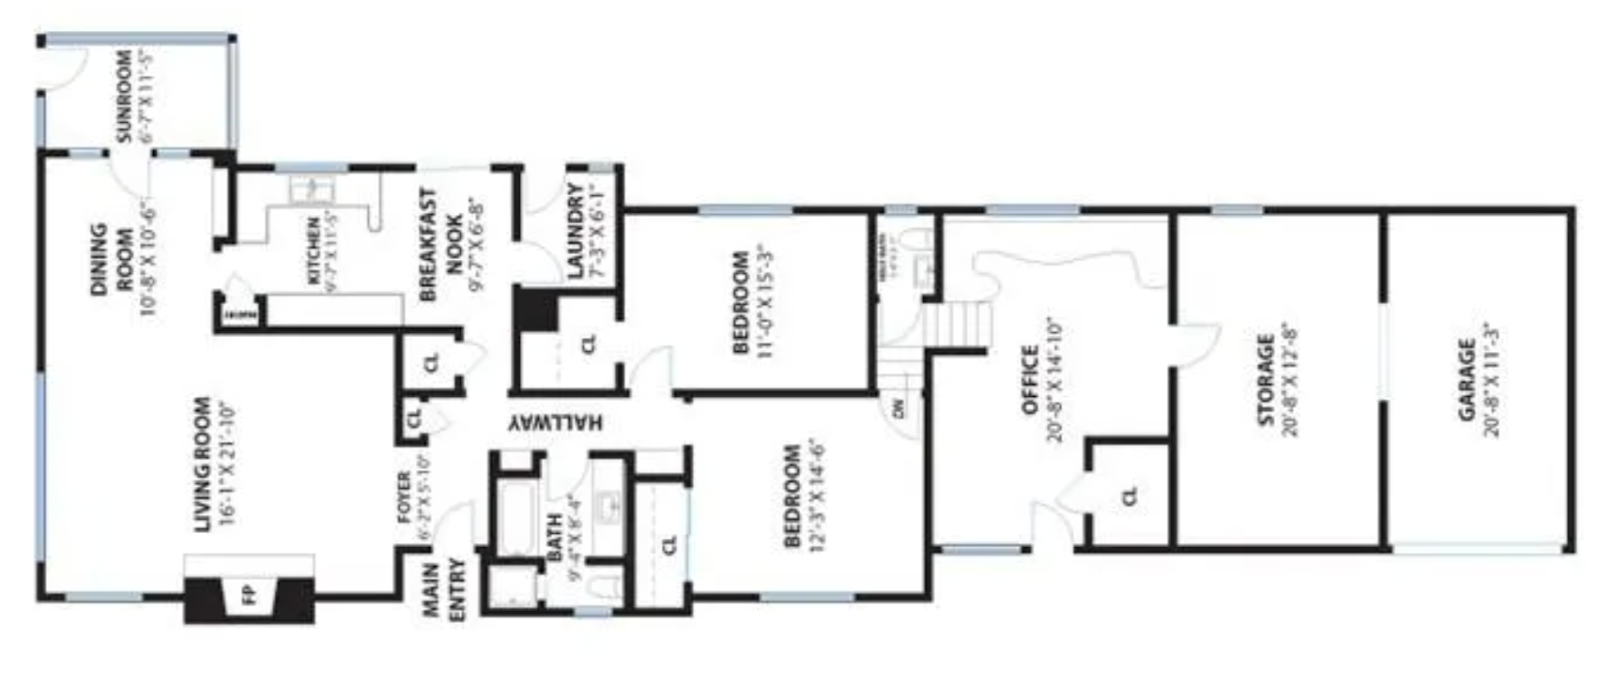
Here's the layout:

Blueprint of 2-bedroom house

Office #1: Built-in desk

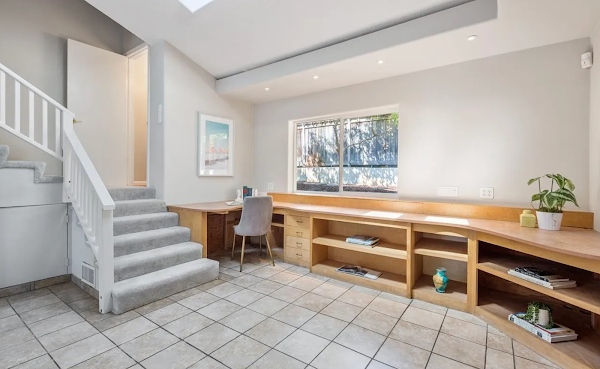
The first obvious candidate for a home office was the "office" area, which even has a built-in desk. See how perfect it looks from the realtor's photos?

Photo of office with built-in desk

Which of us should take that? I'm often doing live streaming or video recording, so I need good lighting, good backdrop, and a high likelihood of people not moving through the space. I realized that desk wasn't a good fit for me, as it lacked all those things, so my partner put his multi-monitor setup there and has been quite happy with it since.


Office #2: Window desk

My next idea was to put a desk next to the window on the sunny side of the office and put a room divider behind me.

Blueprint showing desk next to window in office area

I tried this for a few days but realized that my partner's days are chock full of meetings, and I was constantly distracted by his fairly loud voice or I was constantly distracting him with my own loud voice. Even with our noise-cancelling headphones, we were too loud to be in the same air space, and were both convinced that the other one was definitely the loudest. I feared our relationship could not survive such a setup! 😤


Office #3: Closet desk

Our downstairs office area has a small room that was likely intended as an office, but is surprisingly well accessorized: a strip of very bright adjustable lights on the ceiling, multiple power outlets, and even a door. I decided I would attempt to use that closet as my office, and hoped that the door/wall would muffle the sound sufficiently.

Blueprint showing desk inside closet in office area

And thus begins a long, expensive, and ultimately futile adventure in trying to make a closet into something it's not...


Acoustic treatment

My first goal was to improve the room's acoustic characteristics, as small rooms suffer from bad audio due to reflections on the walls/corners. This involved:

Photo of purple and pink sound panels on wall behind a monitor

Soundproofing

My next goal was to reduce the sound from my partner. This is notably a *distinct* goal from the first one, as this has to do with how waves travel through the walls, not how they travel within the walls. This involved:

  • Moving a bookcase against one of the external walls (mass reduces sound waves)
  • Attaching acoustic tiles to the door
  • Giving up on those tiles, hiring contractor to replace hollow core door with solid core door (most internal doors are hollow core for cost reasons, but solid core is much better for sound reduction)
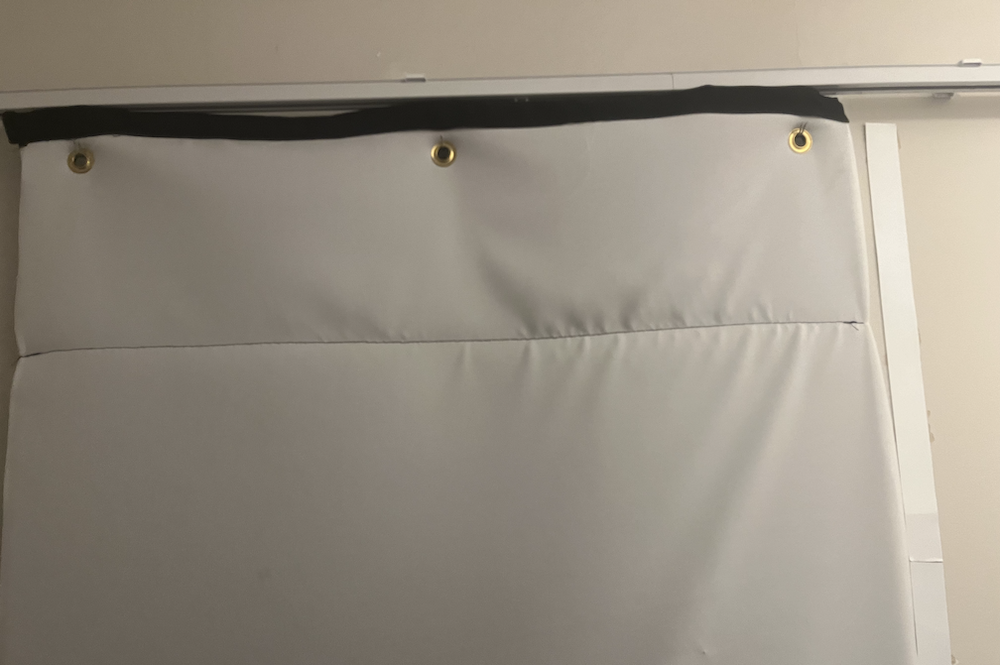
  • Hanging an acoustic curtain in front of the door, on a curtain track so I could move it in front of door during meetings
  • Affixing magnetic strips around the door frame and sewing magnetic buttons onto that acoustic curtain, so that I could try to seal it around the door during meetings. (I never managed to achieve a tight seal, however).
Photo of acoustic curtain on a curtain track in front of door

Ultimately, I achieved a pretty high level of sound reduction, enough so that I could at least stream and attendees didn't seem to notice disruptive background sound. I could still hear my partner in recordings, so I tried to only do recordings when he wasn't in meetings (which was rare!), or I did post-processing to remove noise.


Lighting

The best lighting is actual daylight in front of you, not overhead office lights. So I tried...

  • Replacing the existing office lights with very warm toned lights
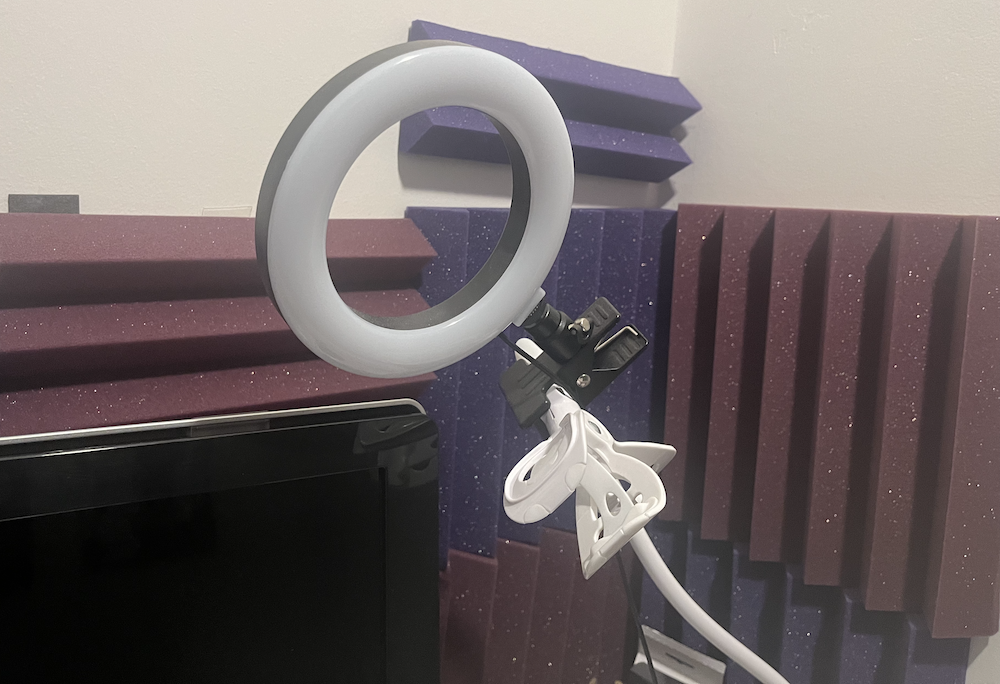
  • Positioning a ring light using an adjustable arm
  • Buying Camo studio so I could more easily use my iPhone as a camera (better quality than most webcams)
  • Buying a wall mount holder to hold the iPhone at the right spot above my monitor
  • Buying LED lights for a little glow behind me
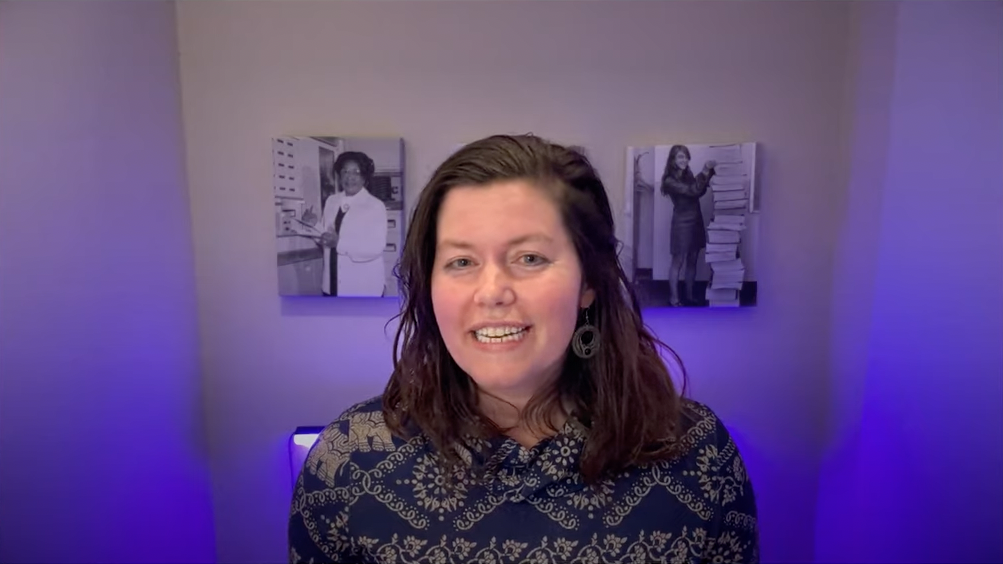
  • Hanging up canvas prints of famous women in STEM (printed at Walgreens photos) so that my backdrop wasn't just a dull gray
Photo of ring light Photo of iPhone wall mount

That improved my lighting to acceptable levels, I think, but you can judge for yourself by watching a video recorded with the lighting setup or checking the screenshot below.

Photo of Pamela in front of a purple-hued wall

Air quality management

As I myself started attending more meetings and doing longer streams, I started to worry about the air quality in my little office. Was I getting enough oxygen? Was I unintentionally decreasing my brain's ability to think? I first installed an Airthings air quality monitor to discover that my CO2 levels were indeed getting pretty high for meetings over an hour (1500+). Improving the air quality consisted of...

  • Hiring a contractor to install a grill in the office wall abutting the storage room and affixing a shelf to a wall in that storage room, so that fresh air could flow in.
  • Hiring same contractor to fix the window in that storage room so that I could keep the window open with a screen on all day without inviting the local wildlife in as well.
  • Buying a remote-controlled fan to forcibly blow the air in from the storage room when I could see my CO2 levels getting high.
Photo of ventilation grill in wall Photo of fan on shelf outside ventilation grill

That setup did actually work, and I was able to pull off a 6-hour live stream in my little closet, with decent CO2 levels throughout the stream. It was annoying to try to remember to open the window at start of the day and close it end of the day, so usually I'd just remember once a week to open the windows to freshen up the air in the storage room.


Temperature control

That closet had no particular means of temperature control like the rest of our house, and neither did the storage room beyond the grill. In the winter, I stayed comfortable enough by using a space heater at the start of the day while monitoring the air quality in case it increased VOCs (which it didn't seem to).

But then summer started. And oh wow, it got pretty hot (high 70s) in that little room, even with the fan, and I found it affected my ability to function well in meetings. We had also recently upgraded to a heat pump system in the rest of the house, complete with air conditioning, and I found myself fantasizing of a well conditioned office.


Office #4: Bedroom

After all that, this is the point where I finally decided that the closet-office just wasn't meant to be. I had already spent thousands upgrading it -- did I really want to spend thousands more fixing the temperature issues?

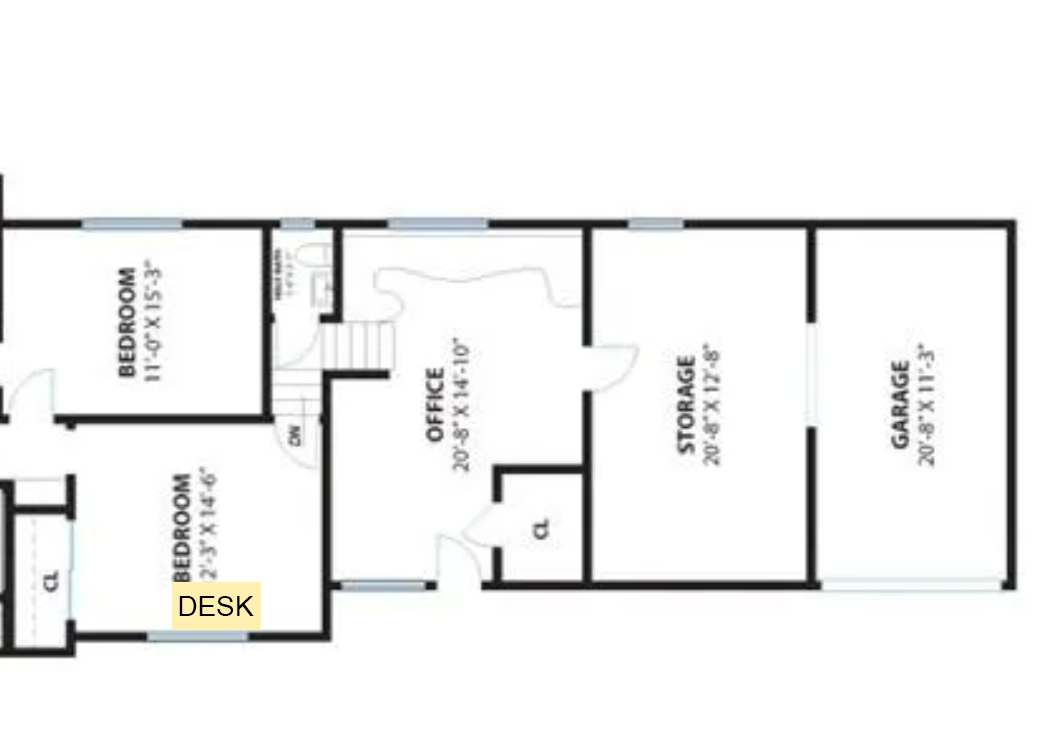
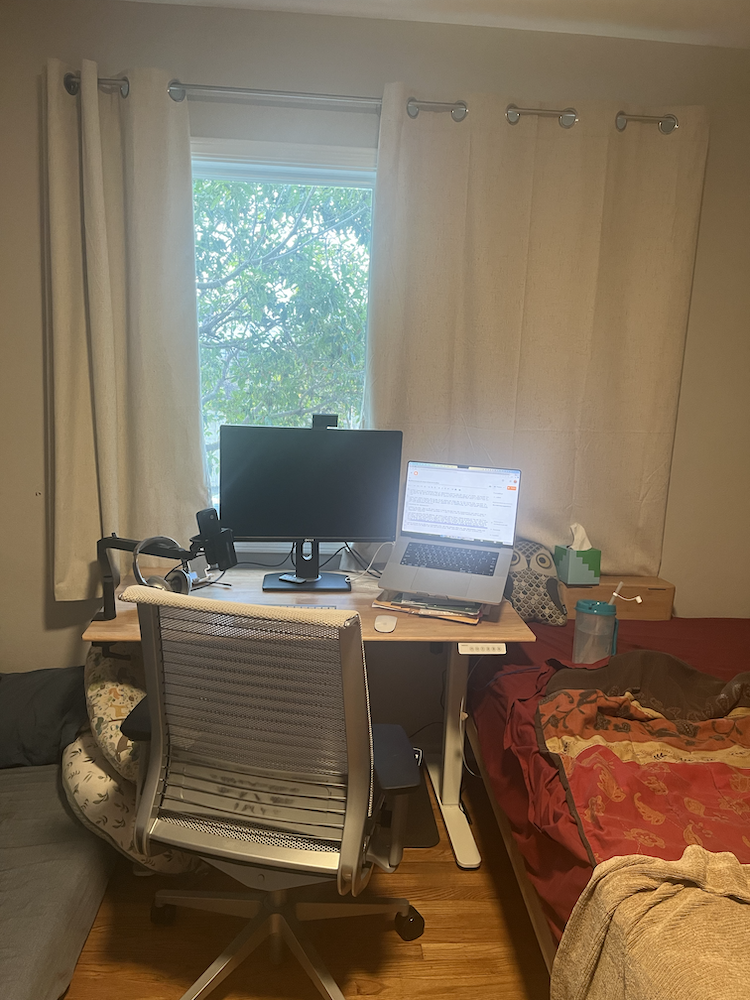
I moved upstairs into our bedroom, and setup a tiny office there, wedged between our bed and the floor bed that I share with our toddler.

Blueprint showing desk in bedroom Photo of desk wedged between two beds

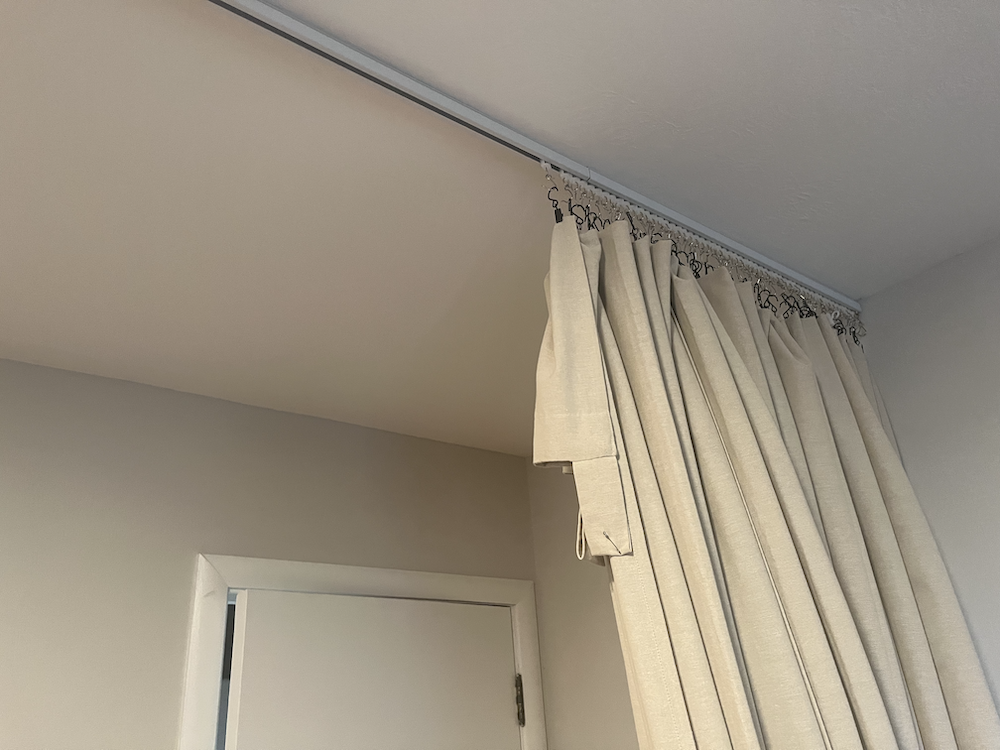
To avoid my partner showing up on streams when he walks past me, I put up a curtain on a track (a wider version of the track used in the closet-office), and I start off each day by moving my curtain into place.

Photo of linen curtain on a ceiling curtain track

I reduce sound by closing the door and keeping my toddler's noise machine on during the day. As it turns out, just being on a different level helps a lot in reducing sound. I still struggle to make recordings without hearing my partner in the background, but it's basically the same level as it was inside the fully upgraded closet. Sigh!

I've written up my tale as a cautionary tale, but also because there are some improvements I made that may legitimately be helpful for your own office setup. TLDR: sometimes a closet is just a closet.

Friday, October 27, 2023

Strategies for managing dependencies for Python samples

A big part of my job in Python advocacy at Microsoft is to create and maintain code samples, like examples of how to deploy to Azure using FastAPI, Flask, or Django. We've recently undergone an effort to standardize our best practices across samples. Most best practices are straightforward, like using ruff for linting and black for PEP8 formatting, but there's one area where the jury's still out: dependency management. Here's what we've tried and the ways in which they have failed us. I'm writing this post in hopes of getting feedback from other maintainers on the best strategy.

Unpinned package requirements files

Quite a few of our samples simply provide a requirements.txt without versions, such as:


quart
uvicorn[standard]
langchain
openai
tiktoken
azure-identity
azure-search-documents
azure-storage-blob

The benefit of this approach is that a developer installing the requirements will automatically get the latest version of every package. However, that same benefit is also its curse:

  • What happens when the sample is no longer compatible with the latest version? The goal of our samples is usually somewhat orthogonal to the exact technologies used, like getting an app deployed on App Service, and we generally want to prioritize a working sample over a sample that is using the very latest version. We could say, well, we'll just wait for a bug report from users, and then we'll scramble to fix it. But that assumes users will make reports and that we have the resources to scramble to fix old samples at any point.
  • What if a developer bases their production code off the sample, and never ends up pinning versions? They may end up deploying that code to production, without tests, and be very sad when they realize their code is broken, and they don't necessarily know what version update caused the breakage.

So we have been trying to move away from the bare package listings, since neither of those situations are good.

Pinned direct dependencies

The next step is a requirements.txt file that pins known working versions of each direct dependency, such as:


quart==0.18.4
uvicorn[standard]==0.23.2
langchain==0.0.187
openai[datalib]==0.27.8
tiktoken==0.4.0
azure-identity==1.13.0
azure-search-documents==11.4.0b6
azure-storage-blob==12.14.1

With this approach, we also set up a dependabot.yaml file so that GitHub emails us every week when new versions are available, and we run tests in GitHub actions so that we can use the pass/fail state to reason about whether a new version upgrade is safe to merge.

I was pretty happy with this approach, until it all fell apart one day. The quart library brings in the werkzeug library, and a new version came out of the werkzeug library that was incompatible with the pinned version of quart (which was also latest). That meant that every developer who had our sample checked out suddenly saw a funky error upon installing requirements, caused by quart trying to use a feature no longer available in werkzeug. I immediately pinned an issue with workarounds for developers, but I still got DMs and emails from developers trying to figure out this sudden new error in previously working code.

I felt pretty bad as I'd heard developers warning about only pinning direct dependencies, but I'd never experienced an issue like this first-hand. Well, now I have, and I will never forget! I think this kind of situation is particularly painful for code samples, where we have hundreds of developers using code that they didn't originally write, so we don't want to put them in a situation where they have to fix a bug they didn't introduce and lack the context to quickly understand.

Compiled direct & indirect dependencies

I made a pull request for that repo to use pip-tools to compile pinned versions of all dependencies. Here's a snippet of the compiled file:


uvicorn[standard]==0.23.2
    # via -r app/backend/requirements.in
uvloop==0.17.0
    # via uvicorn
watchfiles==0.20.0
    # via uvicorn
websockets==11.0.3
    # via uvicorn
werkzeug==3.0.0
    # via
    #   flask
    #   quart

I assumed naively that I had it all figured out: this was the approach that we should use for all repos going forward! No more randomly introduced errors!

Unfortunately, I started getting reports that Windows users were no longer able to run the local server, with an error message that "uvloop is not supported on Windows". After some digging, I realized that our requirement of uvicorn[standard] brought in certain dependencies only in certain environments, including uvloop for Linux environments. Since I ran pip-compile in a Linux environment, the resulting requirements.txt included uvloop, a package that doesn't work on Windows. Uh oh!

I realized that our app didn't actually need the additional uvloop requirement, so I changed the dependency from uvicorn[standard] to uvicorn, and that resolved that issue. But I was lucky! What if there was a situation where we did need a particular environment-specific dependency? What approach would we use then?

I imagine the answer is to use some other tool that can both pin indirect dependencies while obeying environment conditionals, and I know there are tools like poetry and hatch, but I'm not an expert in them. So, please, I request your help: what approach would avoid the issues we've run into with the three strategies described here? Thank you! 🙏🏼

Thursday, September 28, 2023

Using SQLAlchemy 2.0 in Flask

Way back in January, the very popular Python ORM SQLAlchemy released version 2.0. This version makes SQLAlchemy code much more compatible with Python type checkers.


Typed model classes

Here's a SQLAlchemy 2.0 model with typed columns:

class BlogPost(Base):
    __tablename__ = "blog_post"
    id: Mapped[int] = mapped_column(primary_key=True)
    title: Mapped[str] = mapped_column(String(30))
    content: Mapped[str]

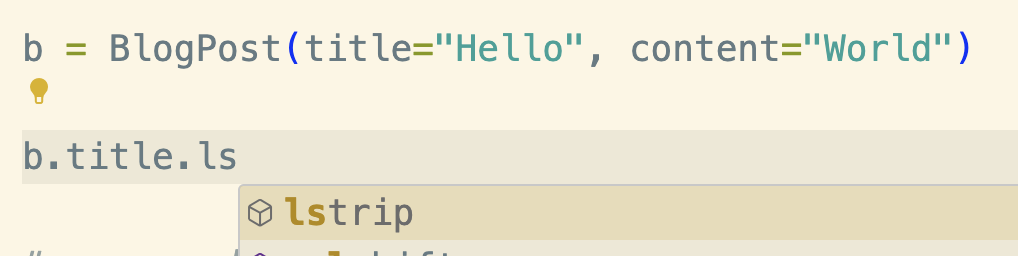
When you're using an IDE that understands type annotations (like VS Code with the Python extension), you can then get intellisense for those columns, like suggestions for functions that can be called on that data type.

Screenshot of intellisense suggestion for id column

You can also run a tool like mypy or pyright to find out if any of your code is using types incorrectly. For example, imagine I wrote a function to process the BlogPost model above:

def process_blog_posts(posts: list[BlogPost]):
    for post in posts:
        post.title = post.title.upper()
        post.id = post.id.upper()

Then running mypy would let me know if my code was using the typed columns incorrectly:

$ python3 -m mypy main_sqlalchemy.py 
main_sqlalchemy.py:30: error: "int" has no attribute "upper"  [attr-defined]

Adding support to Flask-SQLAlchemy

I have recently begun to use type annotations more heavily in my code (especially for class and function signatures) so I was excited to try out SQLAlchemy 2.0. But then I realized that almost all of my usage of SQLAlchemy 2.0 was inside Flask apps, using the Flask-SQLAlchemy extension, and at the time, it did not support SQLAlchemy 2.0. What's a girl to do? Add support for it, of course!

I experimented with several ways to support SQLAlchemy 2.0 and eventually settled on a proposal that would be compatible with (hopefully all) the ways to customize SQLAlchemy 2.0 base classes. You can can choose for their base class to inherit from DeclarativeBase or DeclarativeBaseNoMeta, and you can add on MappedAsDataclass if they'd like to use dataclass-like data models.

A few examples:

class Base(DeclarativeBase):
  pass
     
db = SQLAlchemy(model_class=Base)

class Todo(db.Model):
     id: Mapped[int] = mapped_column(primary_key=True)
     title: Mapped[str] = mapped_column(nullable=True)
class Base(DeclarativeBase, MappedAsDataclass):
  pass
     
db = SQLAlchemy(model_class=Base)
     
class Todo(db.Model):
    id: Mapped[int] = mapped_column(init=False, primary_key=True)
    title: Mapped[str] = mapped_column(default=None)

The pull request was rather large, since we decided to default the documentation to 2.0 style classes, plus I parameterized every test to check all the possible base classes. Thanks to helpful reviews from the community (especially lead Flask maintainer David Lord), we were able to merge the PR and release SQLAlchemy 2.0 support on September 11th.


Porting Flask apps to SQLAlchemy 2.0

Since the release, I've been happily porting sample Flask applications over to use the new style models in SQLAlchemy 2.0, and also using the opportunity to make sure our code doesn't use the legacy way of querying data as well.

Here are a few pull requests that show the changes needed:

Of course, as those are samples, there wasn't a lot of code to change. In a complex production codebase, it will be a much bigger change to upgrade all your models. Hopefully you have tests written before making the change, so you can ensure they're made in a backwards compatible way.


Additional resources

As you're upgrading your models to new-style models, make sure you look through both the SQLAlchemy docs and the Flask-SQLAlchemy docs for examples of what you're trying to accomplish. You can even search through each GitHub repository for additional examples, as some situations that aren't in the docs are still covered in unit tests. The SQLAlchemy docs can be daunting in their scope, so I recommend bookmarking their ORM quickstart and Migration cheatsheet.

In addition to those docs, check out this great summary from Miguel Grinberg on the 2.0 changes. If you prefer learning via video, check out my video series about SQLAlchemy 2.0 on the VS Code channel.

If you do run into any issues with porting your Flask app to SQLAlchemy 2.0, try to figure out first if it's a Flask-SQLAlchemy issue or a core SQLAlchemy issue. Many of the Flask-SQLAlchemy issue reports are in fact just SQLAlchemy issues. You can discuss SQLAlchemy issues in their GitHub discussions and discuss Flask-SQLAlchemy issues in our GitHub discussions or Discord.